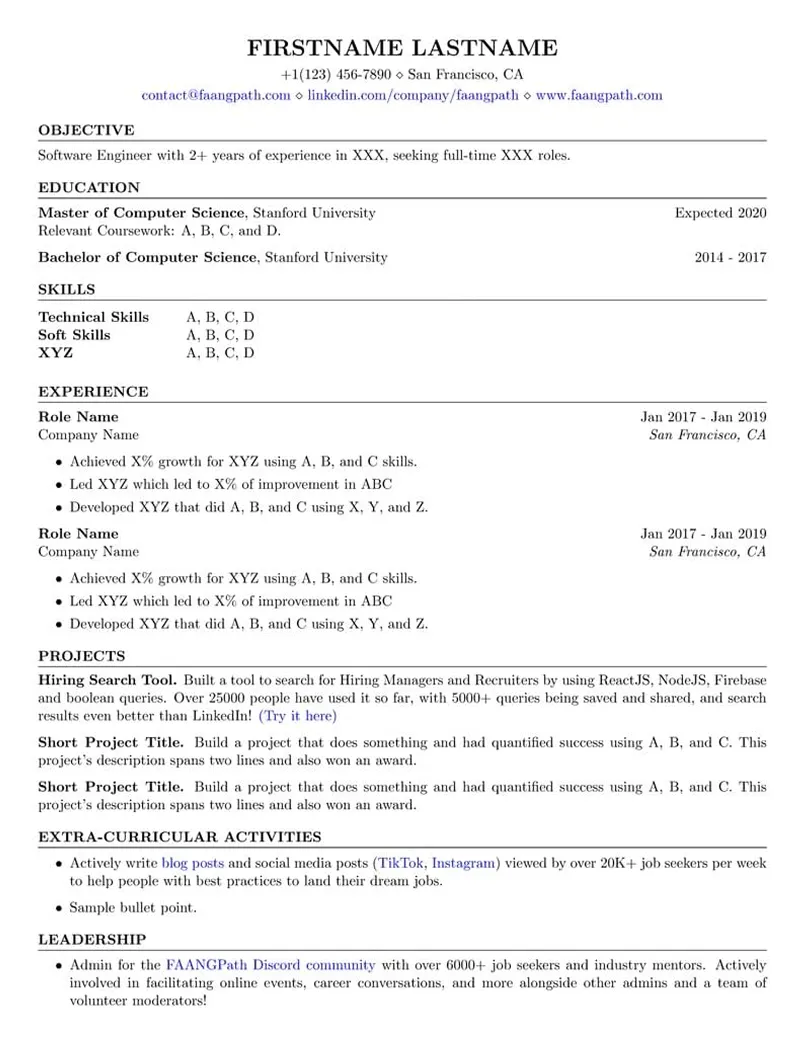
(312) 555-0118 ◇ Chicago, IL
teodora.ilic@example.com ◇ linkedin.com/in/teodora-ilic ◇ teodorailic.com
Site reliability engineer with 5 years keeping production systems healthy, currently on the SRE team of a trading platform that serves 2 million customers and peaks at 45,000 requests per second. Raised availability of core services from 99.9% to 99.98%, cut mean time to recovery from 52 minutes to 14, and cut on-call pages 60% through alert clean-up and automation. Believes reliability is built in design reviews, not just during incidents.
Coursework in Operating Systems, Computer Networks, Distributed Systems, and Systems Programming.
Also holds the HashiCorp Certified Terraform Associate credential.
- Support a trading platform for 2 million customers at peaks of 45,000 requests per second.
- Raised availability of 12 core services from 99.9% to 99.98% with SLOs and error budget policy.
- Cut mean time to recovery from 52 minutes to 14 with runbooks, tracing, and 1-click rollbacks.
- Ran Kubernetes clusters for 90 services on Google Cloud for a logistics software company.
- Cut on-call pages 60% by removing 140 noisy alerts and automating 8 common fixes.
- Wrote Terraform modules for 25 environments, cutting new environment setup from 2 days to 1 hour.
- Built 10 Grafana dashboards for core services used by the on-call team every day.
- Wrote a Python script to clean up unused cloud disks, saving about $3,000 a month.
- Received a full-time offer for 2021 at the end of the 12-week internship.
SLO and Error Budget Programme. Defined SLOs for 12 core services with product owners, built burn-rate alerts in Prometheus, and set an error budget policy that slows releases when budgets run low, which raised availability from 99.9% to 99.98%.
Faster Incident Recovery. Added distributed tracing with OpenTelemetry, wrote 30 runbooks, and built 1-click rollbacks in the deployment pipeline, which cut mean time to recovery from 52 minutes to 14.
Market Open Load Testing. Built a load test that replays market open traffic at 2 times peak against a staging copy, run before every major release, which found 5 capacity limits before they reached production.
- Speaker on alert design at a Chicago SRE meetup with about 200 attendees.
- Contributor to an open source Kubernetes operator, with 7 merged pull requests.
- Volunteer IT helper for a community radio station, maintaining its 2 servers.
- Lead postmortem reviews for about 25 incidents a year across 8 engineering teams.
- Run production readiness reviews for about 10 new services a year.
- Mentor 2 junior engineers on on-call practice and Kubernetes troubleshooting.

.webp)


.webp)


%20Which%20Should%20You%20Use.webp)