Resumes
August 13, 2026

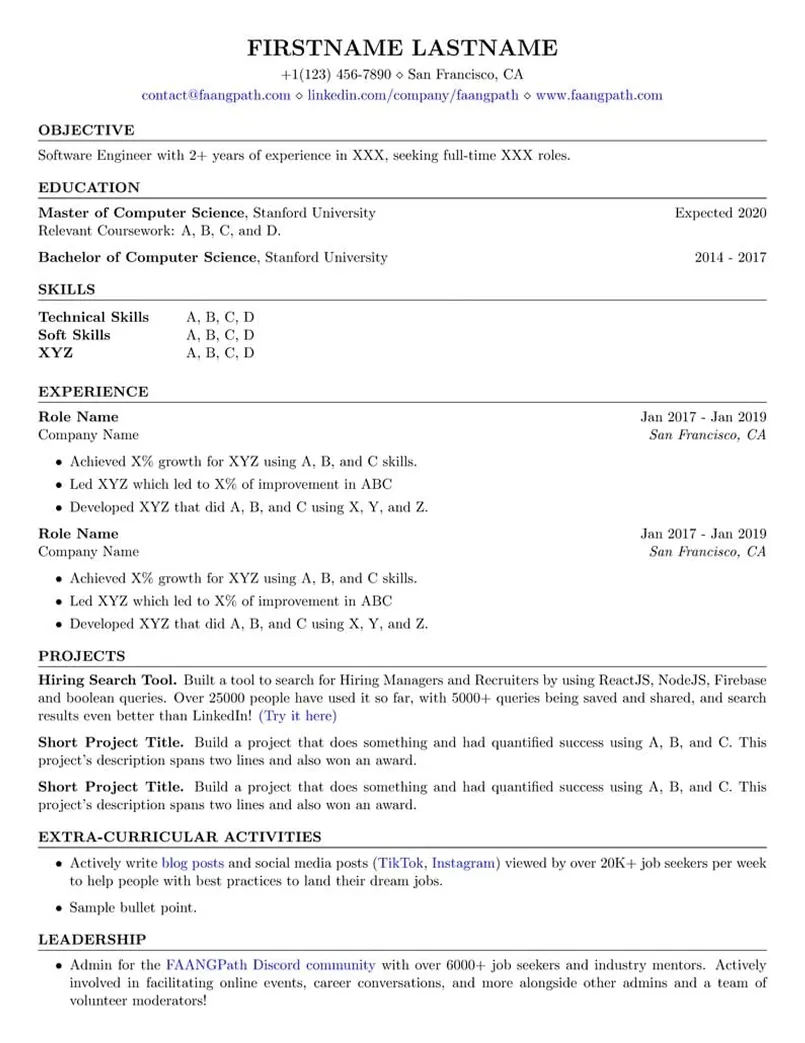

A strong data scientist resume should show models that reached production and the business metric each one moved. Highlight the scale of the data and users, model results stated as a product or financial outcome with a before and after, experiments run, and the deployment and monitoring work that kept a model useful after launch. Name your libraries and platforms explicitly, because Python, SQL, and the specific tooling are filtered on. State your level plainly, since an intern, a fresh graduate, a career changer, and a senior lead are hired on different evidence. Use the examples below to see how to turn modelling work into clear, results-focused resume achievements.
Meet Helena Sorensen, a fictional data scientist owning churn and recommendation models for a 4 million user product. This example shows mid-level work measured by the product metric that moved, validated in controlled experiments.
(206) 555-0174 ◇ Seattle, WA
helena.sorensen@example.com ◇ linkedin.com/in/helena-sorensen ◇ helenasorensen.com
Data scientist with 6 years building models that ship, currently owning churn and recommendation models for a subscription product with 4 million users. Cut monthly churn 18% with a retention model now driving 3 automated interventions, and lifted recommendation click-through 27% across 2 model generations. Measures work by the product metric that moved, not by model accuracy alone.
Thesis on causal inference for observational product data.
Coursework in Probability, Linear Algebra, Optimisation, and Computer Science.
Retention Model. Built a churn model that scores 4 million users weekly and feeds 3 automated interventions. Monthly churn fell 18% in a holdout comparison, and the uplift analysis showed which intervention worked for which segment.
Recommendation Rebuild. Replaced a popularity-based recommender with a learned ranking model across 2 generations, lifting click-through 27% across 9 experiments. The second generation added freshness signals that the first had ignored.
Demand Forecasting. Built a hierarchical forecasting model across 40,000 products that cut stockouts 22% and overstock 15%, with the forecast error reported by category so buyers could see where to trust it.
Meet Vikram Sethi, a data science graduate with a master's degree, an internship, and competition results but no full-time role yet. This example shows how a thesis model in real use and public projects with documented reasoning carry a resume at the start.
(217) 555-0139 ◇ Champaign, IL
vikram.sethi@example.com ◇ linkedin.com/in/vikram-sethi ◇ vikramsethi.com
Data science graduate seeking a first full-time role, holding a master's degree, a 4-month internship, and a thesis model that a university research group now uses. Built a demand model during the internship that beat the incumbent by 19% on holdout error, placed in the top 3% of a 4,000-team forecasting competition, and has 3 public projects with documented reasoning. No professional title yet, so the code is public.
GPA 3.9; thesis on forecasting crop yield from satellite imagery, adopted by a university research group.
Coursework in Algorithms, Databases, Machine Learning, and Statistics; graduated with honours.
Forecasting Competition. Placed in the top 3% of about 4,000 teams in a public retail forecasting competition with a gradient boosting ensemble, and published a write-up explaining which features mattered and which did not.
Crop Yield Thesis. Built a yield model from satellite imagery across 400 fields and 3 seasons, with honest reporting of where it fails, which is why a research group of 8 adopted it rather than a more complex alternative.
Public Portfolio. Maintains 3 public projects, each with a README that states the question, the approach, the result, and the limitations, because that is what a reviewer actually needs to see.
Meet Lorelei Fischer, a master's student 3 months into a 6-month internship. This example is written on work already delivered during the internship, including a model that reached production review, rather than on coursework alone.
(607) 555-0126 ◇ Ithaca, NY
lorelei.fischer@example.com ◇ linkedin.com/in/lorelei-fischer ◇ loreleifischer.com
Master's student in applied statistics, 3 months into a 6-month data science internship at a healthcare analytics company. Built a readmission risk model that reached production review, wrote 40 SQL queries now used by 2 analyst teams, and presents weekly to a team of 9. An internship resume written on work already delivered, with the semester of coursework behind it.
Expected 2027; GPA 3.9 with coursework in Statistical Learning, Bayesian Methods, and Experimental Design.
Graduated with honours; senior thesis on regression methods for panel data.
Readmission Risk Model. Built a 30-day readmission model on 180,000 records, tuned for calibration rather than only discrimination because clinicians act on the probability. It reached production review 3 months into the internship.
Cohort Definitions. Wrote 3 reusable cohort definitions in SQL after finding that 2 analyst teams were counting patients differently, which had produced 2 conflicting reports on the same question.
Panel Data Thesis. Compared regression methods for panel data on a 40,000-observation dataset as a senior thesis, with a section on when each method gives a misleading answer.
Meet Tariq Mansour, 14 months into a first modelling role after 4 years as a business intelligence analyst. This example shows the career changer path, where knowing the data deeply becomes the advantage rather than a gap.
(571) 555-0192 ◇ Arlington, VA
tariq.mansour@example.com ◇ linkedin.com/in/tariq-mansour ◇ tariqmansour.com
Entry level data scientist 14 months into a first modelling role after 4 years as a business intelligence analyst at the same company. Built a lead scoring model that raised sales conversion 23% on scored leads, shipped 2 models to production, and brings 4 years of knowing exactly where the data comes from and what it means. The analyst years are the advantage, not a gap.
9-month part-time programme covering supervised learning, model evaluation, and deployment, completed while working full time.
Coursework in Econometrics, Statistics, and Data Analysis; minor in Computer Science.
Lead Scoring Model. Built a lead scoring model on 4 years of pipeline history and shipped it into the CRM so sales could see the score where they work. Conversion on scored leads rose 23% in a 3-month controlled comparison.
Analyst to Data Scientist Transition. Completed a 9-month machine learning programme while working full time, built a portfolio project on company data with permission, and used it to make the case for an internal move.
Metric Definition Standard. Defined 30 company metrics with documented SQL logic as an analyst, which ended 3 conflicting revenue figures and became the foundation the modelling team now builds features on.
Meet Beatriz Cunha, 2 years into a first data science role at a logistics company. This example sits between intern and mid-level, with owned production models, on-call responsibility, and second-year scope described as it is.
(619) 555-0118 ◇ San Diego, CA
beatriz.cunha@example.com ◇ linkedin.com/in/beatriz-cunha ◇ beatrizcunha.com
Junior data scientist 2 years into a first role at a logistics company, owning 2 production models and contributing to 3 more. Cut delivery time prediction error 31% with a model now shown to 200,000 customers a day, and built the anomaly detection that catches about 40 routing failures a week before customers report them. Second-year scope described as it is.
GPA 3.8; coursework in Machine Learning, Statistics, Databases, and Optimisation.
Passed on first attempt while working full time; also completed a 30-hour course in MLOps in 2025.
Delivery Time Prediction. Rebuilt the delivery time estimate with route, depot, and weather features, cutting error 31%. The estimate is shown to about 200,000 customers a day, so the monitoring and retraining schedule mattered as much as the model.
Routing Anomaly Detection. Built detection on route telemetry that flags about 40 failures a week, from stalled vehicles to missed depot scans, and routes them to operations before a customer notices.
Volume Forecasting Prototype. Built a depot-level package volume forecast as an intern that cut error 14% and became the basis for the production forecast after joining full time.
Meet Mikkel Andersen, a senior data scientist leading a team of 6 across 14 production models. This example shows senior scope: fraud and pricing systems with large financial results, model governance, and people developed.
(415) 555-0162 ◇ San Francisco, CA
mikkel.andersen@example.com ◇ linkedin.com/in/mikkel-andersen ◇ mikkelandersen.com
Senior data scientist with 11 years, leading pricing and fraud modelling for a payments platform processing $18B a year. Built the fraud model that cut losses $24M a year at a 0.3% false decline rate, led dynamic pricing that added $31M in annual margin, and leads a team of 6 across 14 production models. Senior means owning the outcome, the model, and the people who maintain it.
Dissertation on sequential decision methods; 4 peer-reviewed publications.
Graduated with highest honours; coursework in Probability, Analysis, and Computer Science.
Fraud Model. Built a real-time fraud model scoring every transaction in under 40 milliseconds, cutting losses $24M a year. The constraint was false declines, held at 0.3% because each one costs a merchant a customer.
Dynamic Pricing. Led pricing across 40,000 merchants using a sequential decision approach rolled out in stages over 9 months. Margin rose $31M a year and merchant churn did not move, which was the condition for continuing.
Experimentation Platform. Designed the platform that runs about 400 experiments a year across 20 teams, with guardrails that stop a test automatically when a core metric degrades.
Sign up now to access Careerflow’s powerful suite of AI tools and take the first step toward landing your dream job.